Tuan Duc Ngo

Working on 3D & 4D Vision

I’m a PhD student in Computer Science at UMass Amherst, advised by Prof. Evangelos Kalogerakis and Prof. Chuang Gan.

I was a research intern at Adobe Research. Previously, I interned at Snap Research, working with Dr. Chaoyang Wang on 4D reconstruction.

Prior to my Ph.D., I was an AI Research Resident at VinAI Research, working closely with Dr. Khoi Nguyen.


PhD in CS
Sep 2023 -
Research Intern
Jun 2026 -
Research Intern
May 2025 - Nov 2025
Research Intern
May 2024 - May 2025
AI Research Resident
Aug 2021 - Jul 2023

News

  • [09/2026] VolFill is accepted to NeurIPS 2026 [code].
  • [06/2026] I will join Meta as a Research Intern.
  • [02/2026] DAGE is accepted to CVPR 2026 [code].
  • [05/2025] I joined Adobe Research as a Research Intern.
  • [02/2025] 4Real-Video is accepted (highlight) to CVPR 2025.
▼ Show more

Publications

* indicates equal contribution.

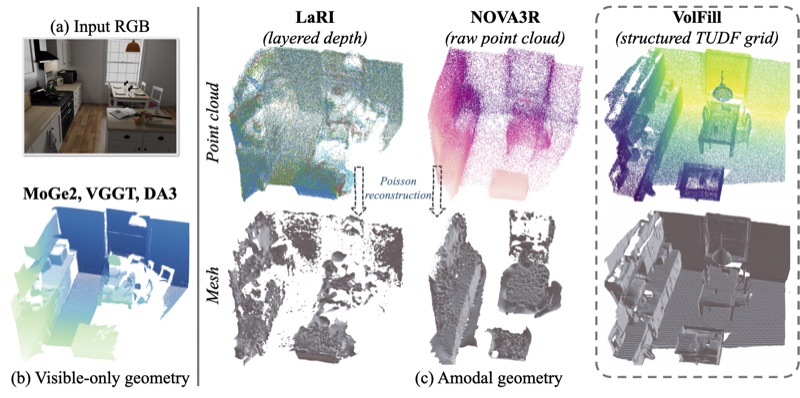
VolFill: Single-View Amodal 3D Scene Reconstruction with Volumetric Flow Matching

VolFill: Single-View Amodal 3D Scene Reconstruction with Volumetric Flow Matching

NeurIPS, 2026

Reconstructs the complete 3D scene from a single RGB image, including surfaces hidden behind visible geometry, by generating a structured volumetric representation instead of regressing per-pixel depth.

DAGE: Dual-Stream Architecture for Efficient and Fine-Grained Geometry Estimation

CVPR, 2026

Recovers sharp, view-consistent geometry and accurate camera poses from uncalibrated videos at up to 2K resolution, using a dual-stream transformer that separates global context from fine detail.

DELTAv2: Accelerating Dense 3D Tracking

Preprint, 2025

Speeds up dense, long-range 3D point tracking by 5–100× while keeping state-of-the-art accuracy, through coarse-to-fine trajectory expansion and cheaper correlation features.

4Real-Video: Learning Generalizable Photo-Realistic 4D Video Diffusion

CVPR, 2025 Highlight

Generates photorealistic 4D videos, a grid of frames spanning both time and viewpoint, with a two-stream diffusion transformer that keeps them consistent across views and over time.

DELTA: Dense Efficient Long-range 3D Tracking for Any video

ICLR, 2025

Tracks every pixel in 3D across long monocular videos, running over 8× faster than prior methods while achieving state-of-the-art dense 2D and 3D tracking accuracy.

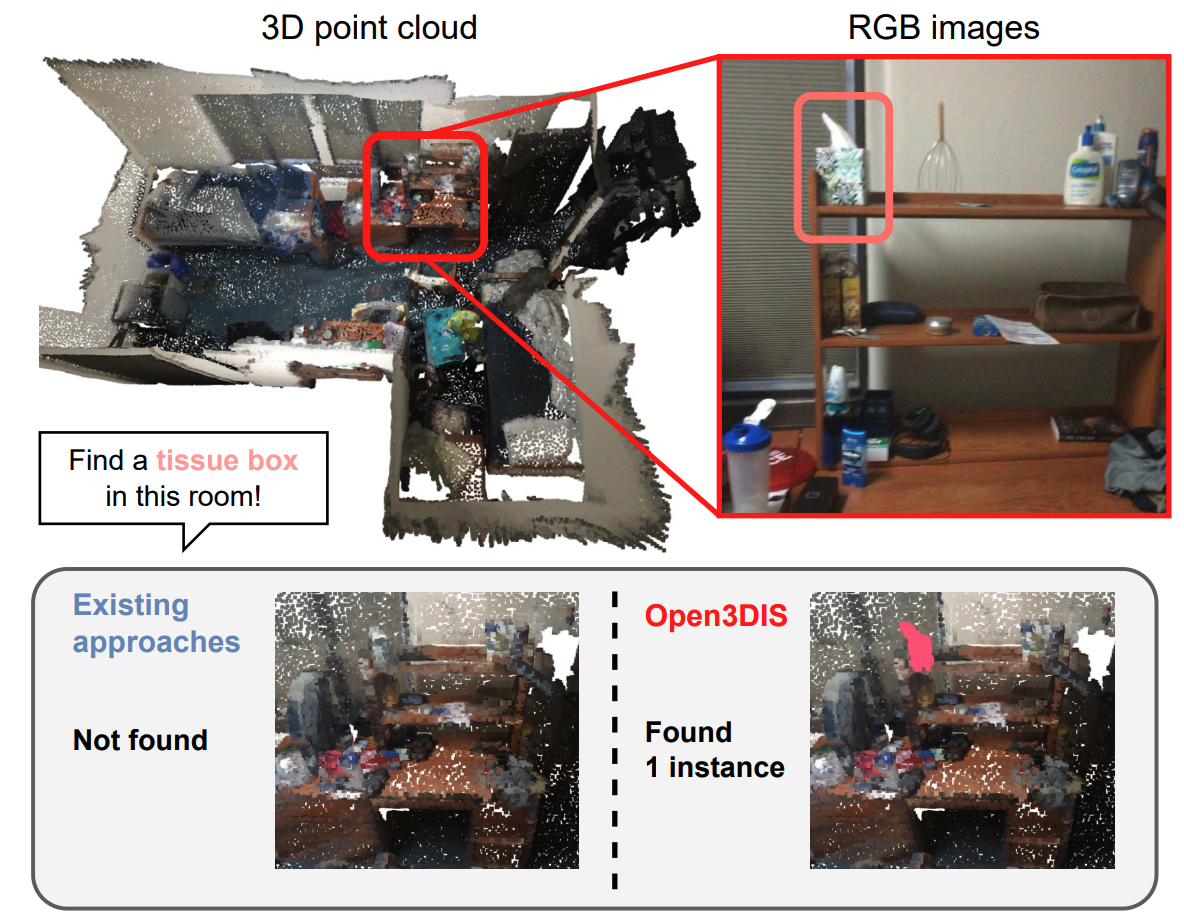
Open3DIS: Open-vocabulary 3D Instance Segmentation with 2D Mask Guidance

Open3DIS: Open-vocabulary 3D Instance Segmentation with 2D Mask Guidance

CVPR, 2024

Segments 3D object instances from open-vocabulary queries by lifting 2D instance masks across frames into 3D proposals, recovering small and geometrically ambiguous objects that 3D-only methods miss.

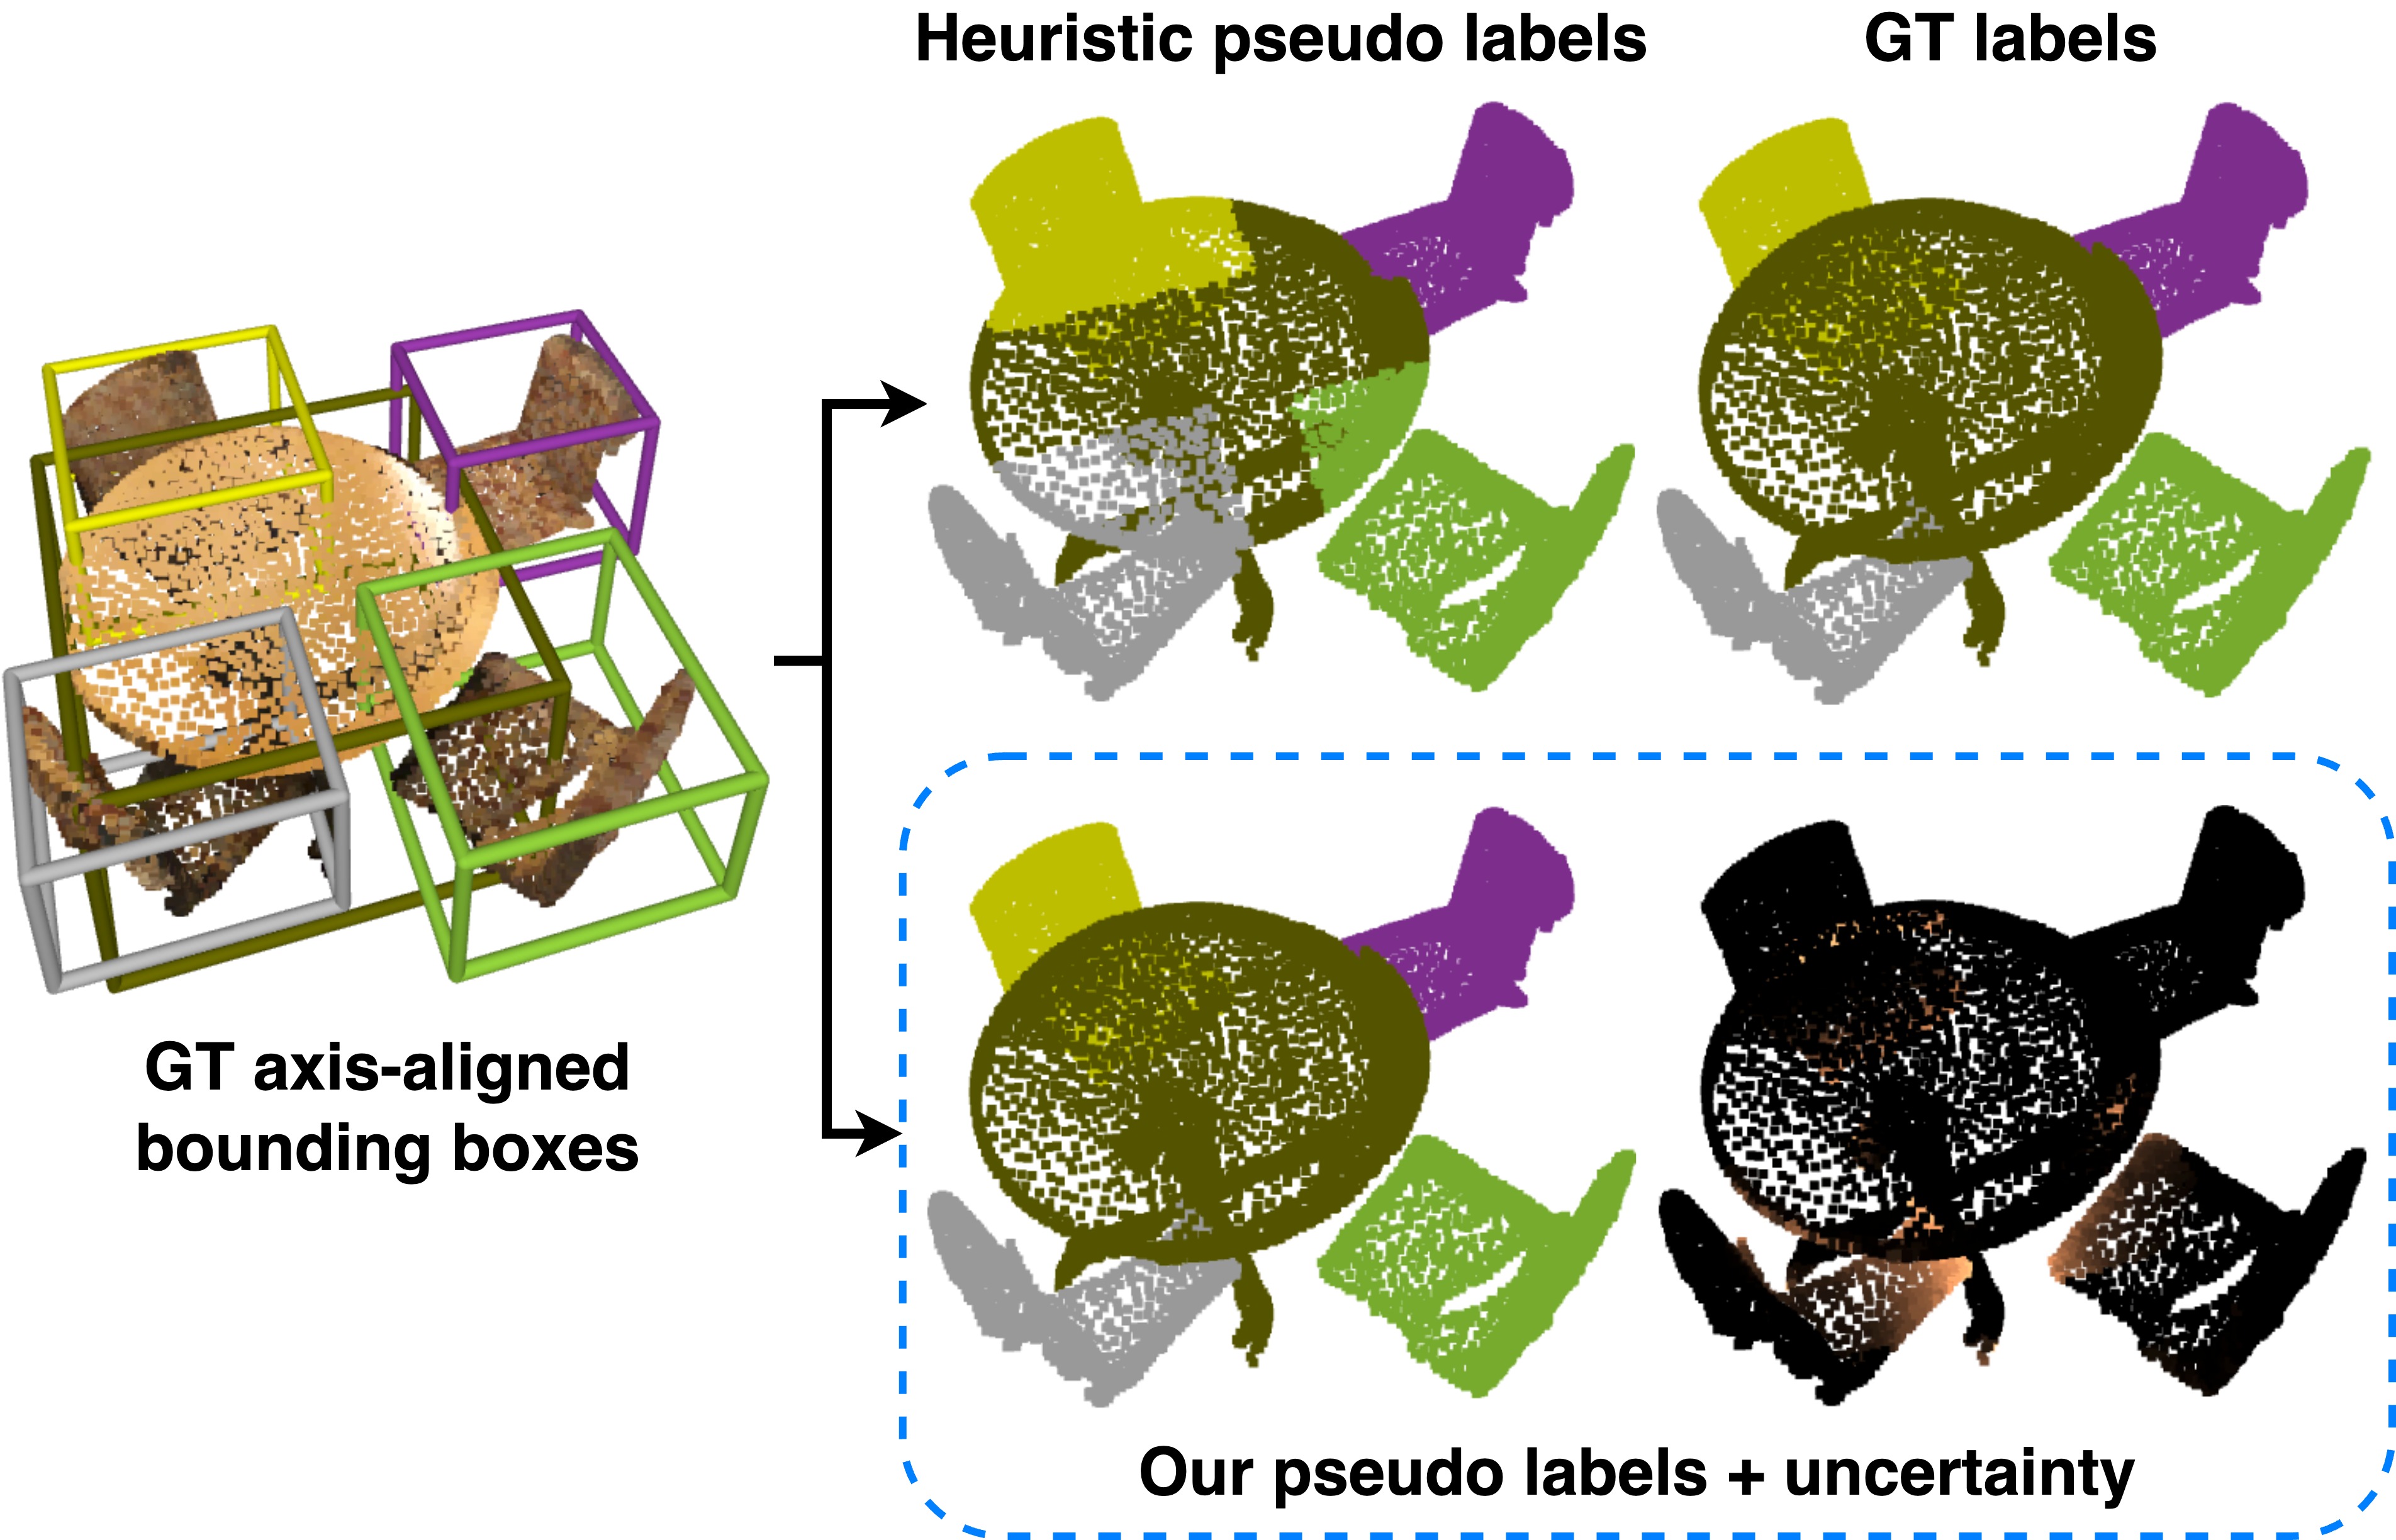
GaPro: Box-Supervised 3D Point Cloud Instance Segmentation Using Gaussian Processes as Pseudo Labelers

GaPro: Box-Supervised 3D Point Cloud Instance Segmentation Using Gaussian Processes as Pseudo Labelers

Tuan Duc Ngo, Binh-Son Hua, Khoi Nguyen
ICCV, 2023

Learns 3D point cloud instance segmentation from bounding boxes alone, using Gaussian Processes to turn box annotations into pseudo instance masks, and performs competitively with fully supervised methods.

ISBNet: a 3D Point Cloud Instance Segmentation Network with Instance-aware Sampling and Box-aware Dynamic Convolution

ISBNet: a 3D Point Cloud Instance Segmentation Network with Instance-aware Sampling and Box-aware Dynamic Convolution

Tuan Duc Ngo, Binh-Son Hua, Khoi Nguyen
CVPR, 2023

Segments 3D point cloud instances without clustering, using instance-aware sampling and box-aware dynamic convolution, and sets new state-of-the-art results on ScanNetV2, S3DIS, and STPLS3D.

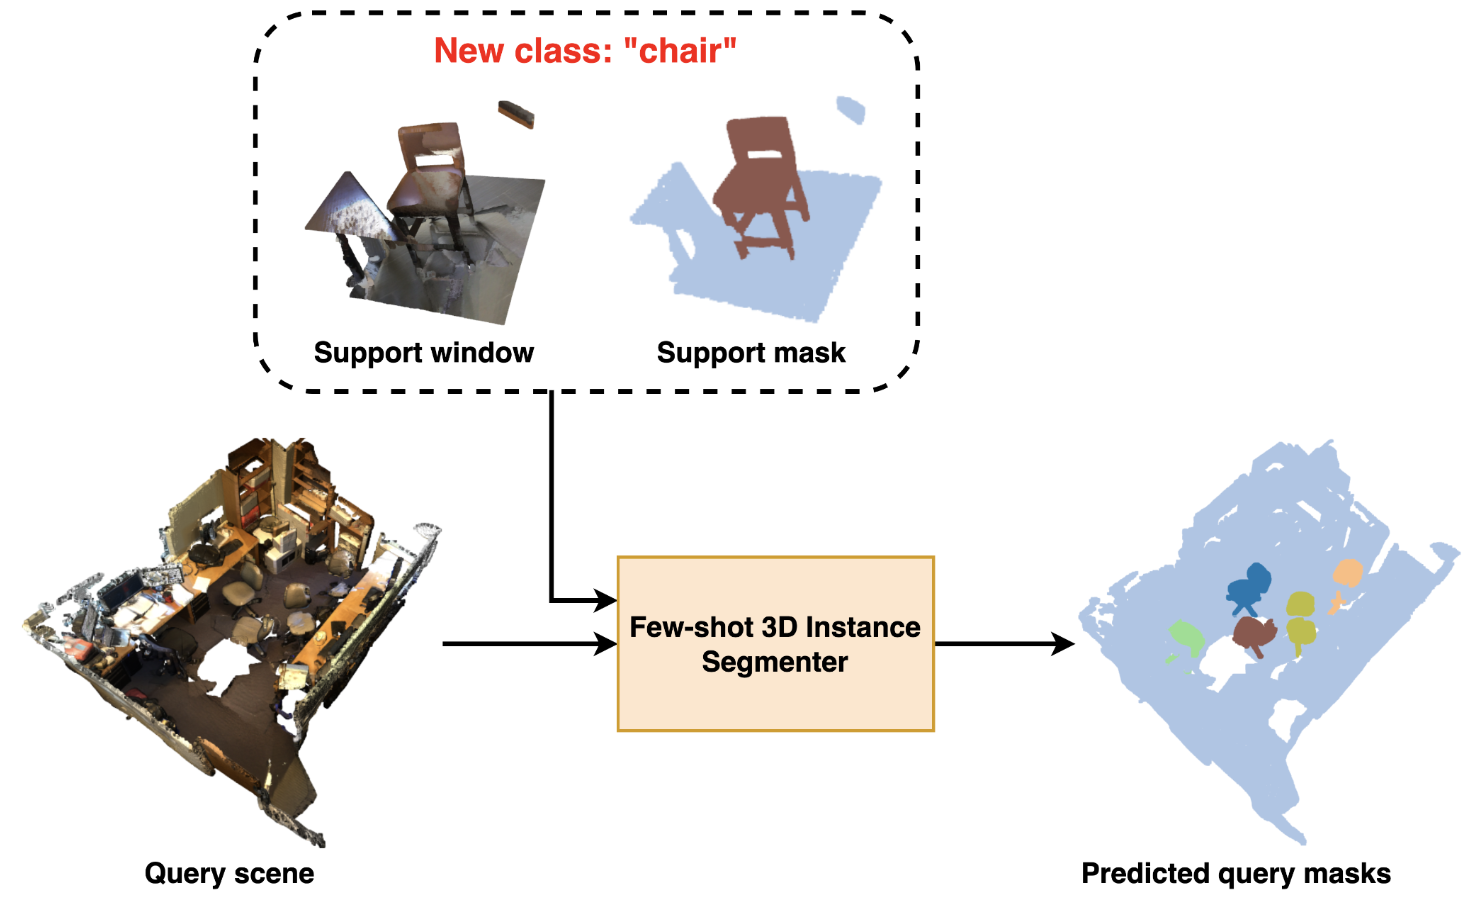
Geodesic-Former: A Geodesic-Guided Few-Shot 3D Point Cloud Instance Segmenter

Geodesic-Former: A Geodesic-Guided Few-Shot 3D Point Cloud Instance Segmenter

Tuan Duc Ngo, Khoi Nguyen
ECCV, 2022

Introduces few-shot 3D point cloud instance segmentation and tackles it with a transformer guided by geodesic distance, which copes with the uneven point density of real 3D scans.

GAC3D: improving monocular 3D object detection with ground-guide model and adaptive convolution

PeerJ, 2021

Improves monocular 3D object detection with a ground-guide model built on the ground-plane assumption and a depth-adaptive convolution.


Academic Services

Conference Reviewer CVPR '24/'25/'26 ICCV '25 ECCV '24/'26 NeurIPS '25 ICLR '26 AAAI '25/'26
Journal Reviewer IEEE Transactions on Image Processing